
Your payment team ships a small fix on Tuesday. By Wednesday morning, reporting is broken, fraud checks are timing out, and someone is blaming the network.
If that sounds familiar, you already understand the problem SOA OS23 is trying to solve.
Enterprise software has spent twenty years swinging between giant monoliths and sprawling microservices that quietly turned into distributed systems nobody fully understood. The SOA OS23 pattern sits in the sensible middle. It keeps the business-service thinking of classic service-oriented architecture and drops the heavy middleware that made it painful.
This article covers what it is, how it differs from traditional SOA and from microservices, what the key features look like in production, and where it falls short. You’ll also get a step-by-step adoption path and straight answers to the questions teams ask most.
What Is SOA OS23?
SOA OS23 is a modern take on service-oriented architecture. Instead of routing everything through one central bus, it splits business capabilities into independent services. Those services talk through defined APIs and event streams, run in containers, and verify identity on every request.
Think of service-oriented architecture OS23 as the old idea of reusable business services, rebuilt for cloud-native infrastructure. Services are packaged with Docker, orchestrated by Kubernetes, and exposed through an API gateway using REST or GraphQL, with contracts written in OpenAPI.
A quick word on the name. Most writers tie the “23” to a 2023-style refresh of SOA thinking, and you’ll see the term used a little differently from site to site. One honest caveat follows from that: the term is not an ISO standard or a single vendor product. It’s an architectural pattern, and teams adapt it in their own ways.
That flexibility is useful, but write your own definition down before you start. Otherwise three teams will build three different versions and call them all the same thing.
TechTrendery.com USA: Your Guide to Tech News, Reviews, and How-To Guides
SOA OS23 vs Traditional SOA
Traditional SOA grew up around application servers and the enterprise service bus. The ESB was powerful, but it became a choke point. Change one mapping and you needed a release window, a change board, and a little prayer.
SOA OS23 architecture pushes logic outward. Each service owns its data and behavior, the gateway handles routing and authentication, and Apache Kafka carries events between services. No single box knows everything, which also means no single box can take everything down.
| Architecture Area | Traditional SOA | SOA OS23 |
| Integration | Central ESB and heavy middleware | API gateways and event streams |
| Deployment | Application servers and slow releases | Containers, Kubernetes, fast rollback |
| Security | Trusted internal network | Zero-trust per-request identity |
| Operations | Basic logs and siloed monitoring | OpenTelemetry, Prometheus, Grafana |
The biggest shift isn’t the tooling. It’s ownership. Under old SOA, a central integration team owned the bus. Here, every service team owns its own contract and answers for it.
SOA OS23 vs Microservices
People mix these up constantly, so let’s settle it. Microservices are a way of building small, independently deployed units. This pattern is a broader architectural approach that happens to use microservices-style building blocks, then adds business-level service contracts, governance, and a plan for connecting existing enterprise systems.
| Question | Microservices | SOA OS23 |
| Main focus | Small deployable units | Reusable business services across the enterprise |
| Governance | Often left to each team | Shared contracts, versioning, and policy |
| Legacy systems | Usually out of scope | Wrapped and exposed through APIs |
| Typical scale | One product or platform | Many products and departments |
If you’re a startup with one product, plain microservices (or even a well-kept monolith) may be enough. If you’re an enterprise with twenty systems that all need to cooperate, the governance side is where this pattern earns its keep.
Key Features of SOA OS23
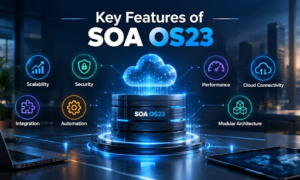
Six traits define the pattern in practice.
Modular Service Design
Each service maps to a business capability: payments, customer profiles, inventory. It has its own codebase, its own database, and its own release cycle.
The first time I saw a team ship a new payment service without touching the fraud or reporting systems, I understood exactly why modular architecture matters in production. Nobody scheduled a meeting. Nobody held their breath. It just shipped. That’s the opposite of a monolithic architecture, where one bad deploy can take the whole building down.
Kubernetes Deployments keep a rollout history, so rolling a bad release back is a single command rather than a weekend project. Fault isolation does the rest: when one service fails, the others keep running.
API-First Communication
Contracts come before code. Teams write the OpenAPI spec, agree on it, then build against it. Front-end, mobile, and integration teams can all work from the same definition instead of waiting for backend code to settle.
This isn’t a fringe habit anymore. Postman’s 2024 State of the API report found that 74% of respondents were API-first, up from 66% the year before, and its 2025 edition pushed that past 80%. APIs have stopped being a side effect of software and become the product teams plan around.
REST handles most traffic. GraphQL suits screens that need data from several services at once. An API gateway sits in front and handles rate limits, routing, versioning, and authentication. And here’s the thing: if a service can’t be described by a clean contract, it isn’t ready to be a service yet.
Event-Driven Messaging
Not every interaction should be a request and a response. When an order is placed, five other systems care: billing, inventory, shipping, fraud, notifications. Calling each one directly creates a tangle of point-to-point links.
Apache Kafka solves this by letting the order service publish one event. Everyone who cares subscribes. New consumers can join later without anyone editing the sender, and the replayable log lets a service that was down catch up when it returns. Use REST when you need an answer right now, and events when you’re announcing that something happened.
Cloud-Native Compatibility
Services ship as Docker containers and run on Kubernetes, with Helm charts making deployments repeatable. The CNCF’s 2023 survey showed 66% of respondents already running Kubernetes in production, with another 18% evaluating it. If your architecture can’t run cleanly on a container platform, you’re swimming against the current.
Kubernetes HPA scales pods on demand, which matters when Black Friday hammers payments but leaves the HR service idle. One catch trips up a lot of teams: the autoscaler needs a Metrics Server and resource requests defined on your containers. Without them, it has nothing to calculate from, and utilization reads as zero.
For small sites or edge nodes, K3s gives you the same model on lighter hardware. The whole setup lines up with CNCF tooling, so you aren’t locked into one vendor’s idea of the cloud.
Observability
Splitting a system into services trades one big problem for many small ones, and the small ones are harder to see. That’s the nature of distributed systems: failures hide in the gaps between components. This is why observability is part of the pattern, not an afterthought.
OpenTelemetry gives you vendor-neutral tracing and metrics. Prometheus collects the numbers, and Grafana turns them into dashboards your on-call engineer can read half-asleep. The payoff is one trace ID that follows a request across ten services, instead of five log files and a guess.
Zero-Trust Security Model
Being inside the network no longer earns trust. NIST’s SP 800-207 frames zero trust as protecting resources rather than network segments, which fits distributed systems that span cloud platforms, edge nodes, and remote teams.
In practice, every request carries an identity, usually a JWT issued through OAuth 2.0 and OpenID Connect. Services follow least privilege, so each one can reach only what it needs. Credentials are short-lived, traffic between services is encrypted, and access decisions happen per request rather than once at login.
Small services don’t make you safer by themselves. Strong identity, policy enforcement, and auditing do. Get this part right early, because retrofitting it is miserable.
Badseed Tech Carpio: Is This Gliding Wrist Rest Actually Worth It?
Benefits of SOA OS23 for Enterprise Teams
The real payoff shows up in release speed. Small services mean small deployments, and a Kubernetes rollback takes seconds instead of an all-hands incident call.
Scaling gets cheaper too. You scale the hot services, not the entire application. If checkout spikes during a sale, you add replicas there instead of buying hardware for reporting, search, and admin pages that are sitting idle.
Observability finally becomes usable. Honestly, tracing alone convinces most skeptical operations teams.
Teams gain independence. One group can pick a different language or database as long as the contract holds. Hiring gets easier as well, because this is the stack most engineers want on their resumes.
Then there’s the business side, which is what your CFO cares about. Faster releases mean features reach customers sooner. Fewer outages mean fewer refunds and support tickets. Reusable services mean the second project costs less than the first, because the customer or payment service already exists. And a gradual migration path means you modernize without a risky big-bang rewrite.
Connecting Legacy Systems
Legacy integration is where architecture projects either pay off or stall. This pattern handles it well because it doesn’t demand a full rewrite on day one. You wrap old systems with APIs, translate formats at the edge, and replace the hardest pieces one service at a time.
MuleSoft’s API-led connectivity model is a useful way to organize the work. System APIs sit directly on the legacy source, such as an ERP or mainframe. Process APIs orchestrate business logic across systems. Experience APIs shape the data for each app or channel. The structure stops teams from wiring every new application straight into an old database.
Apache Camel approaches the same problem from the message side. A Camel route is a series of steps that moves a message from a source to a destination, transforming it along the way. That’s handy when you need to bridge a legacy SOAP service to a newer REST or event-driven flow.
| Tool or Pattern | What It Does Well | Best Use Here |
| MuleSoft API-led connectivity | Separates system, process, and experience layers | Gradual modernization of ERP and CRM |
| Apache Camel routes | Transforms and routes messages between endpoints | Protocol translation and data reshaping |
| API gateway | Central auth, throttling, and versioning | One controlled front door for old and new services |
My advice: expose stable business records first. Customer, order, payment, and inventory are the usual starters. Don’t try to modernize every internal workflow at once.
Real World Applications
IoT and Edge Computing
A factory with thousands of sensors can’t ship every reading to the cloud. Devices publish over MQTT, a lightweight publish-subscribe protocol that works well over unstable networks. Local gateways run small services on K3s that filter and aggregate the data, and only the useful part goes upstream.
AWS IoT Greengrass fits when you want a managed edge runtime that processes data on the device and syncs selected results later. The practical rules: process locally first, buffer data when connectivity drops, send summaries rather than raw streams, and reuse the same packaged components across sites.
Financial Services
Banks and payment companies already think in service boundaries: identity checks, fraud scoring, authorization, settlement, ledger updates, notifications. This pattern lets a fraud service evolve weekly while the ledger service stays locked down.
Security rules matter most here. PCI DSS v4.0.1 requires multi-factor authentication for all access into the cardholder data environment (Requirement 8.4.2), and it became mandatory on March 31, 2025. Perimeter-only thinking doesn’t survive that. Applying identity, policy, and audit controls at every service boundary does. Kafka gives auditors a replayable event log they can actually trust.
Healthcare
Hospitals run a zoo of systems that were never meant to meet. HL7 FHIR gives them a shared, API-friendly language for exchanging health data. FHIR-facing services expose patient records through APIs with tight OAuth scopes, and Apache Camel or MuleSoft wrap older systems so they can speak FHIR without a rewrite.
Even if healthcare isn’t your field, it’s a strong example of why standard APIs matter: they make old records usable in new products.
Challenges and When Not to Use It
I’d be doing you a disservice if I only sold the upside.
Operational complexity is real. Ten services means ten deployments, ten sets of logs, and a network between them that can fail in new ways. If you don’t have monitoring and on-call habits in place, you’ll feel it fast.
Distributed data is hard. Once each service owns its database, a single transaction can no longer span them. You’ll need patterns like sagas and eventual consistency, and your team needs to understand why a balance might be briefly out of date.
Governance can rot. Without versioning rules and contract reviews, you end up with a distributed monolith: all the network overhead, none of the independence.
It’s overkill sometimes. A small team with one product and modest traffic usually does better with a well-structured monolith. Don’t adopt a pattern because it’s fashionable. Adopt it because your pain matches what it fixes.
How to Start Implementing SOA OS23
Starting out doesn’t mean rewriting your estate. Please don’t. The teams that succeed pick one painful, well-bounded area and prove the pattern there.
Phase 1: Pick and define (weeks 1-2). Choose one business capability that hurts today, such as notifications or pricing. Write its OpenAPI contract before touching code.
Phase 2: Build and ship (weeks 3-6). Containerize it with Docker and deploy it on Kubernetes using a Helm chart. Put it behind an API gateway with OAuth 2.0 and JWT validation. Add OpenTelemetry from day one, with Prometheus and Grafana on top.
Phase 3: Run it and learn (weeks 7-10). Keep that single service in production. Watch what breaks. Set resource requests so HPA works, and rehearse a rollback.
Phase 4: Expand carefully. Add a second service, then wrap a legacy system with Apache Camel or MuleSoft. Introduce Kafka when you have a real event to publish, not before.
Mistakes I See Teams Repeat
- Splitting services too small, so every feature touches six of them.
- Sharing one database between services, which quietly rebuilds the monolith.
- Skipping contract versioning, then breaking consumers on a Friday.
- Treating security as a later phase.
- Measuring success by service count instead of release speed and incident rate.
FAQs
What is SOA OS23?
A modern service-oriented architecture pattern. Independent services, API-first contracts, containers, and zero-trust security. Think classic SOA without the central bus and the weekend deployment marathons.
How is SOA OS23 different from traditional SOA?
Traditional SOA centralizes everything in an ESB. This pattern decentralizes it. Gateways and events replace the bus, containers replace application servers, and every request proves its identity instead of leaning on the internal network.
Is SOA OS23 the same as microservices?
Close cousins, not twins. Microservices are about small, independently deployed units. This pattern adds business-level contracts, governance, and a plan for connecting existing enterprise systems. Microservices are a common way to build the services inside it.
Can SOA OS23 connect legacy systems?
Yes, and it’s one of its best tricks. Wrap the old system with Apache Camel or MuleSoft, expose a clean REST or FHIR API, and let new services talk to that. Don’t rewrite what already works.
Is implementing SOA OS23 difficult?
The technology is the easy part. Kubernetes and Helm are well documented. The hard part is team habits: ownership, contracts, on-call duty. Start with one service and you’ll be fine. Start with fifty and you’ll regret it.
Why does SOA OS23 matter for business?
Because it turns IT from a bottleneck into a release engine. Features ship sooner, outages shrink, and reusable services make every new project cheaper than the last. That’s a budget conversation, not just an engineering one.
Does SOA OS23 require Kubernetes?
Not strictly, but in practice you’ll want it. Containers need an orchestrator for scaling, rollbacks, and self-healing. If full Kubernetes feels heavy, K3s is a lighter way to get the same model.
What is the future of SOA OS23?
Bright, and boring in the best way. Expect more platform engineering, more OpenTelemetry standardization, more workloads at the edge on K3s, and more services designed to be called by AI agents. The pattern will keep absorbing whatever the CNCF ships next.
Final Verdict
Adopt it, but gradually. SOA OS23 gives enterprise teams faster releases, tighter security, and clearer ownership without the old bus bottleneck. Small team with one product? Hold off. Tangled enterprise systems? Pick one painful service this quarter, wrap it, and ship it. Then drop a comment with the service you chose first, and share this with the architect on your team who’s tired of Friday deploys.
Stop Wasting Hours on Confusing Product Pages
Too many tabs, too many buzzwords, too little time. SoftwareCora gives you clear, honest guides and comparisons, so you can pick the right tool with confidence.
Know a gadget or tool that isn’t what its name suggests? Read our Write For Us guidelines and send your topic pitch today.

1 Comment
Pingback: Software CC (Change Control): Workflow, Risk Scores & Audits